Introduction to the CEDAR Query API
Welcome to the new CEDAR Query API (CQ-API)! We have now made it possible to programmatically query CEDAR using multiple endpoints, enabling users to complete most queries available from the CEDAR home page and work with the data directly in their preferred environment. We hope this help article provides additional context on the CEDAR API.
If you have any questions or feedback, please contact us at cedar@lji.org.
What is the CQ-API?
The CQ-API is built upon a PostgREST platform that allows for transparent access to the Postgres tables on the backend. Each table can be queried through individual endpoints, described in this interactive Swagger documentation.
What endpoints are available?
The CQ-API provides two main types of endpoints: search and export. The search endpoints contain multiple fields with information that facilitate programmatic identification and/or filtering of the data of interest, while the export endpoints match the structure and naming conventions of the custom exports on the CEDAR website.
Core search endpoints
- epitope_search
- antigen_search
- tcell_search (assays)
- bcell_search (assays)
- mhc_search (assays)
- tcr_search (receptors)
- bcr_search (receptors)
- reference_search
Export endpoints
- epitope_export
- tcell_export (assays)
- bcell_export (assays)
- mhc_export (assays)
- tcr_export (assays)
- bcr_export (assays)
- reference_export
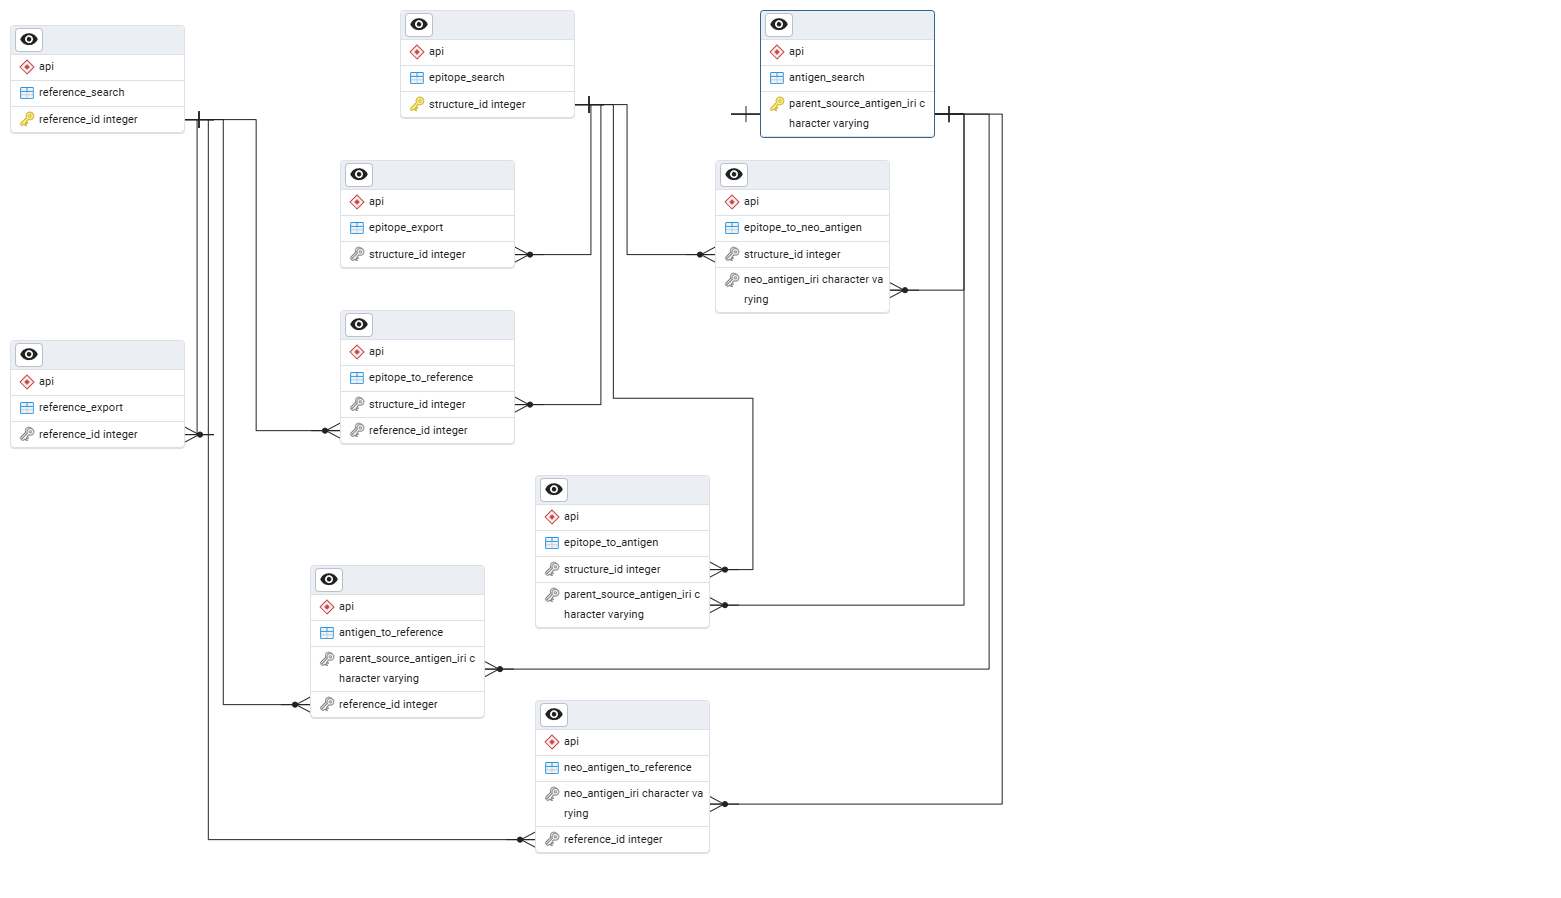
As shown in the Entity Relationship Diagram (ERD), these endpoints are interconnected by different fields (more ERDs can be found in this GitHub repository). We recommend first querying the relevant search table and then using resource embeddings to retrieve the needed data from its associated export table. An example of resource embeddings usage is provided at the end of this document. The entire list of available fields is described in the interactive Swagger documentation.
Supporting endpoints
Additional supporting endpoints are available that map identifiers between the various tables. These endpoints have names like ‘TABLEX_to_TABLEY’. For instance, the ‘bcell_to_reference’ table maps records between the ‘bcell_search’ and ‘reference_search’ records to link related information. Each of these tables has exactly two columns and maps the unique identifiers (fields with a suffix of ‘_id’) between the tables.
An additional endpoint, ‘curie_map’, links CURIE prefixes (e.g., PMID) to their full IRIs. Further details on CURIEs and IRIs can be found below.
The ‘epitope_variant_information’ endpoint maps to neoepitope records, providing detailed somatic mutation data at the protein and genomic levels; the latter is mapped to the human reference genome assembly GRCh38/hg38.
Finally, the ‘api_metrics’ endpoint provides record counts and build dates for the core endpoints.
How to query the CQ-API?
As the CQ-API is based on PostgREST, queries must be performed using its rich and expressive query syntax, described here in detail. Detailed API walkthroughs are available in our CEDAR API GitHub repository as Python notebooks.
The most basic example of querying for the first 10 epitopes is provided here, using the ‘curl’ command.
curl 'https://cedar-api.iedb.org/epitope_search?limit=10' | jq
[
  {
    "structure_id": 1635057,
    "structure_iri": "CEDAR_EPITOPE:1635057",
    "structure_descriptions": [
      "NRNTDGSTDYGILQ + OX(Y10)"
    ],
    "curated_source_antigens": [
      {
        "accession": "P00698.1",
        "name": "Lysozyme C",
        "iri": "UNIPROT:P00698.1",
…
Only the first part of the response is shown, as the full response includes many fields. Note the ‘pipe’ to ‘jq’, used to format the data nicely for display. By default, results are returned in JSON format. If CSV (comma-separated values) format is preferred, an additional header has to be provided in the GET query. The same query would become:
curl 'https://cedar-api.iedb.org/epitope_search?limit=10' -H "accept: text/csv"
The output is not shown, as there are too many fields to display. However, we can limit the output to a subset of fields with the ‘select’ parameter. For example, if we only want the ‘structure_id’ and ‘linear_sequence’ of the first 10 epitopes and we want it returned in CSV format, the query becomes:
curl 'https://cedar-api.iedb.org/epitope_search?limit=10&select=structure_id,linear_sequence' -H "accept: text/csv"

structure_id,linear_sequence
1635057,NRNTDGSTDYGILQ
1635065,NRNTDGSTDYGILQIN
1635069,NRNTDGSTDYGILQIN
1635072,NSGSLSSGVH
1635082,NSWVESQTNGIIR
1635088,NSWVESQTNGIIR
1635099,NTDGSTDYGILQ
1635111,NTQATNRNTDG
1635136,NVINGGSHA
As already mentioned, the search endpoints contain particular fields that facilitate the programmatic identification and filtering of relevant data. One example of these fields is the host_organism_iri_search, which contains the complete taxonomic lineage of the host organism, including all parent taxa. This enables queries at any taxonomic rank (e.g., kingdom, order, species) by matching against the corresponding identifier in the hierarchy. The taxonomies are expressed as IRIs (Internationalized Resource Identifiers), which provide stable links to external resources, such as the NCBI Taxonomy. Let’s include this field to inspect its structure:
curl 'https://cedar-api.iedb.org/epitope_search?limit=10&select=structure_id,linear_sequence,host_organism_iri_search' -H "accept: text/csv"

structure_id,linear_sequence,host_organism_iri_search
1635057,NRNTDGSTDYGILQ,"{NCBITaxon:10090,NCBITaxon:314147,NCBITaxon:40674,taxon:10000067}"
1635065,NRNTDGSTDYGILQIN,"{NCBITaxon:10090,NCBITaxon:314147,NCBITaxon:40674,taxon:10000067}"
1635069,NRNTDGSTDYGILQIN,"{NCBITaxon:10090,NCBITaxon:314147,NCBITaxon:40674,taxon:10000067}"
1635072,NSGSLSSGVH,"{NCBITaxon:10090,NCBITaxon:314147,NCBITaxon:40674,taxon:10000067}"
1635082,NSWVESQTNGIIR,"{NCBITaxon:10090,NCBITaxon:314147,NCBITaxon:40674,taxon:10000067}"
1635088,NSWVESQTNGIIR,"{NCBITaxon:10090,NCBITaxon:314147,NCBITaxon:40674,taxon:10000067}"
1635099,NTDGSTDYGILQ,"{NCBITaxon:10090,NCBITaxon:314147,NCBITaxon:40674,taxon:10000067}"
1635111,NTQATNRNTDG,"{NCBITaxon:10090,NCBITaxon:314147,NCBITaxon:40674,taxon:10000067}"
1635136,NVINGGSHA,"{NCBITaxon:10090,NCBITaxon:314147,NCBITaxon:40674,taxon:10000067}"
1635175,NVMEERKIK,"{NCBITaxon:10090,NCBITaxon:314147,NCBITaxon:40674,taxon:10000067}"
Now, if we want to retrieve epitopes only tested in humans as hosts, the query would be:
curl -g 'https://cedar-api.iedb.org/epitope_search?limit=10&select=structure_id,linear_sequence,host_organism_iri_search&host_organism_iri_search=ov.{NCBITaxon:9606}' -H "accept: text/csv"

structure_id,linear_sequence,host_organism_iri_search
1749239,FPPSDEQLKSGTASVVCLLNNFYPRE,"{NCBITaxon:314295,NCBITaxon:40674,NCBITaxon:9443,NCBITaxon:9606}"
1636089,AEQGAQVTF,"{NCBITaxon:314295,NCBITaxon:40674,NCBITaxon:9443,NCBITaxon:9606}"
1636725,DIEERPKEL,"{NCBITaxon:314295,NCBITaxon:40674,NCBITaxon:9443,NCBITaxon:9606}"
1636805,DMKPKHLL,"{NCBITaxon:314295,NCBITaxon:40674,NCBITaxon:9443,NCBITaxon:9606}"
1636810,DMQRKVEL,"{NCBITaxon:314295,NCBITaxon:40674,NCBITaxon:9443,NCBITaxon:9606}"
1637123,ELGIRHVL,"{NCBITaxon:314295,NCBITaxon:40674,NCBITaxon:9443,NCBITaxon:9606}"
1636881,DTRPKLNAM,"{NCBITaxon:314295,NCBITaxon:40674,NCBITaxon:9443,NCBITaxon:9606}"
1638190,HMFTKEEL,"{NCBITaxon:314295,NCBITaxon:40674,NCBITaxon:9443,NCBITaxon:9606}"
1638744,KIPPTPFSA,"{NCBITaxon:314295,NCBITaxon:40674,NCBITaxon:9443,NCBITaxon:9606}"
1639007,KYLDAEQSY,"{NCBITaxon:314295,NCBITaxon:40674,NCBITaxon:9443,NCBITaxon:9606}"
All the fields in the search endpoints denoted with the suffix ‘_search’ have this ‘tree-like’ structure and are connected to different ontologies, such as ONTIE, GeneOntology, DiseaseOntology, and OntoBee, among others. Further details on CEDAR Ontologies can be found in this article.
Other examples of search endpoint fields supporting complex queries are the neoantigen_bool, viral_antigen_bool, and germline_antigen_bool fields, which behave as the checkboxes on the Epitope Source panel of the CEDAR home page. For example, if we want to retrieve neoantigens and germline antigens, the query would be:
curl -g 'https://cedar-api.iedb.org/epitope_search?limit=10&select=structure_id,linear_sequence&host_organism_iri_search=ov.{NCBITaxon:9606}&or=(neoantigen_bool.eq.1,germline_antigen_bool.eq.1)' -H "accept: text/csv"

structure_id,linear_sequence
1016130,GQAPVKKI
1017692,HETDNMNQI
1018511,HLYLGAAKV
1020205,IEDNELNIVL
1020289,IEKIMAQI
1020696,IHVSDQELQSANASVDDSRLEELK
1022822,IYLNLLNDL
1022413,ITITNDK
1022615,IVIGDEHISF
1025192,KLSEATREL
What are IDs, IRIs, and CURIEs?
Several types of identifiers are used throughout the database to track unique records. First, there are internal integer record identifiers denoted with the suffix ‘_id’, e.g., ‘reference_id’. These are generally in the first field of each table. As they are internal to the CEDAR, they cannot be linked directly to other resources.
Many of the tables in the database also have fields that end in ‘_iri’, e.g., ‘reference_iri’. These are identifiers that resolve uniquely and unambiguously to records both within and outside of the CEDAR. The Internationalized Resource Identifier (IRI) specification includes Uniform Resource Locators (URLs), which we use as globally unique identifiers, e.g., https://cedar.iedb.org/reference/1043674. A shortened version of an IRI, called a CURIE, can be constructed by replacing a portion of the IRI with a common prefix. The above IRI can be represented in CURIE format as ‘IEDB_REFERENCE:1043674.
By querying against the ‘curie_map’ endpoint, it is possible to find prefixes for converting between the two representations, e.g.: https://cedar-api.iedb.org/curie_map?limit=3
curl 'https://cedar-api.iedb.org/curie_map?limit=5&select=curie_prefix,iri_replace' -H "accept: text/csv"

curie_prefix,iri_replace
PMID,https://www.ncbi.nlm.nih.gov/pubmed/?term=
IEDB_REFERENCE,https://www.iedb.org/reference/
IEDB_SUBMISSION,https://www.iedb.org/submission/
IEDB_EPITOPE,https://www.iedb.org/epitope/
IEDB_COMPLEX,https://www.iedb.org/3dViewer.php?complex=
IRIs for Antigens
Only for the ‘antigen_id’ field in the ‘antigen_search’ table, an IRI is used rather than an internal integer record identifier.
Troubleshooting and FAQs
Common issues and idiosyncrasies
Curated vs Parent Terms
There are some terms called “curated”, such as curated_source_antigens, while other similar terms use the phrase “parent”, such as parent_source_antigen_names.
“Curated” refers to the precise source protein isoform that matches exactly what an author referred to as the source of a peptide epitope in a specific publication. The curated_source_antigen will 100% BLAST match to the epitope sequence.
“Parent” refers to a reference protein that serves as a representative protein for all the isoforms to which an epitope was linked in different studies. The parent groups these isoforms together, but it will not always be an exact BLAST match to the epitope sequence.
Similarly, the source_organism_name (shown nested under curated_source_antigens) reflects the precise source organism strain that matches exactly what an author referred to as the source of an epitope in a specific publication. While the parent_source_antigen_source_org_name is the species-level organism name that groups all strains that might ever have been associated with that same epitope across all publications.
This help desk article goes into further detail: Epitope Source.
Results Page Limit & Default Page Size
By default, the CQ-API has a maximum page size of 10,000 records. In practice, this means that queries that result in more than 10,000 results will be divided into pages, and only the first 10,000 records will be returned by the initial query.
NOTE: If a query requires paging, it is critical to also provide the ‘order’ parameter to determine how the rows are sorted. If it is not provided, rows will be returned in a random order, and pages will be inconsistent between queries.
The API will always return a count of the records matching the query, as well as the number of pages of results. This information is embedded in the ‘content-range’ response header, e.g.:
curl -I 'https://cedar-api.iedb.org/antigen_search'

HTTP/1.1 200 OK
Date: Tue, 25 Aug 2026 23:47:29 GMT
Server: postgrest/9.0.1
Content-Range: 0-9999/*
Content-Location: /antigen_search
Content-Type: application/json; charset=utf-8
The server returned the first 10,000 records (indexed as 0-9999). The trailing ‘/*’ indicates that there are more records matching the query, but the total number has not been calculated. To get an exact count of matching records, the header ‘Prefer: count=exact’ must be provided in the GET request.
curl -I 'https://cedar-api.iedb.org/antigen_search' -H 'Prefer: count=exact'

HTTP/1.1 206 Partial Content
Date: Tue, 25 Aug 2026 23:49:01 GMT
Server: postgrest/9.0.1
Content-Range: 0-9999/69941
Content-Location: /antigen_search
Content-Type: application/json; charset=utf-8
Now we can see that there are 69,941 matching records, which would correspond to 7 pages of results. Note that adding this header can be detrimental to query performance.
To retrieve the last page of the results, add the ‘offset’ parameter to the query:
curl -I 'https://cedar-api.iedb.org/antigen_search?offset=60000&order=parent_source_antigen_id' -H 'Prefer: count=exact'

HTTP/1.1 206 Partial Content
Date: Wed, 26 Aug 2026 00:11:34 GMT
Server: postgrest/9.0.1
Content-Range: 60000-69940/69941
Content-Location: /antigen_search?offset=60000&order=parent_source_antigen_id
Content-Type: application/json; charset=utf-8
If an offset is defined that is higher than the number of matching records, an empty result will be returned.
Error messages
Large Query Error - “Cannot enlarge string buffer containing…out of memory”
This message is the result of a large amount of information being returned. Many of the tables in the database contain fields that are information-dense, which can cause buffering issues on the Postgres backend. If a user receives this message, the recommended workflow is to:
- Try adding a ‘limit’ parameter to your query to fetch the first N (e.g., 100) records
- Simultaneously, add the request header ‘Prefer: count=exact’ so you are aware of the total number of records matching the query
- Update the query to filter rows (on field values) or unnecessary columns (using ‘select’) and/or continue to page through the results by adding an ‘offset’ parameter
FAQs
– Can I generate API links from the CEDAR?
Yes. We have recently implemented a new function on the ‘Results’ page that builds API queries reproducing the filters applied on the webpage. For more information, refer to this article: Get API Links from Database Searches.
– Can I query for epitope sequence similarity to BLAST matches at 90%, 80% and 70%?
Unfortunately, the BLAST match options cannot be replicated via the CQ-API, but it can be used for ‘Exact’ and ‘Substring’ queries. For example:
- Exact match (you will want to do an equals search eq.): https://cedar-api.iedb.org/epitope_search?linear_sequence=eq.SIINFEKL
- Substring match (you will want to do a like search with a * wildcard on either side of the search term): https://cedar-api.iedb.org/epitope_search?linear_sequence=like.*SIINFEKL*
– Can I search for multiple epitopes from the CEDAR web interface?
The web interface currently only allows searching one sequence at a time, and we are actively working on implementing this functionality. In the meantime, the CQ-API allows users to simultaneously query for multiple epitope sequences via these endpoints.
– Is there a way to access the number of subjects or response frequency for specific assays through the CQ-API?
Yes, however, these values are not part of the assay search endpoints. To access the additional fields available in the export endpoints while still running standard searches in the search endpoints, one can rely on PostgREST Resource Embedding. This feature allows retrieval of information from another linked endpoint within the current endpoint. For example, in the case of bcell_search:
https://cedar-api.iedb.org/bcell_search?select=*,bcell_export(assay__number_of_subjects_tested,assay__number_of_subjects_positive,assay__response_frequency_)&bcell_id=eq.1384867
As shown in this example, the bcell_search query uses the assay ID to link to the bcell_export information, pulling the specified fields from that endpoint into the existing API call.
Contact information
Contact us via email at cedar@lji.org to provide your feedback.